混音插件套装Nolvra Effects All Plugins Bundle v2026
VST插件格式:
VST3
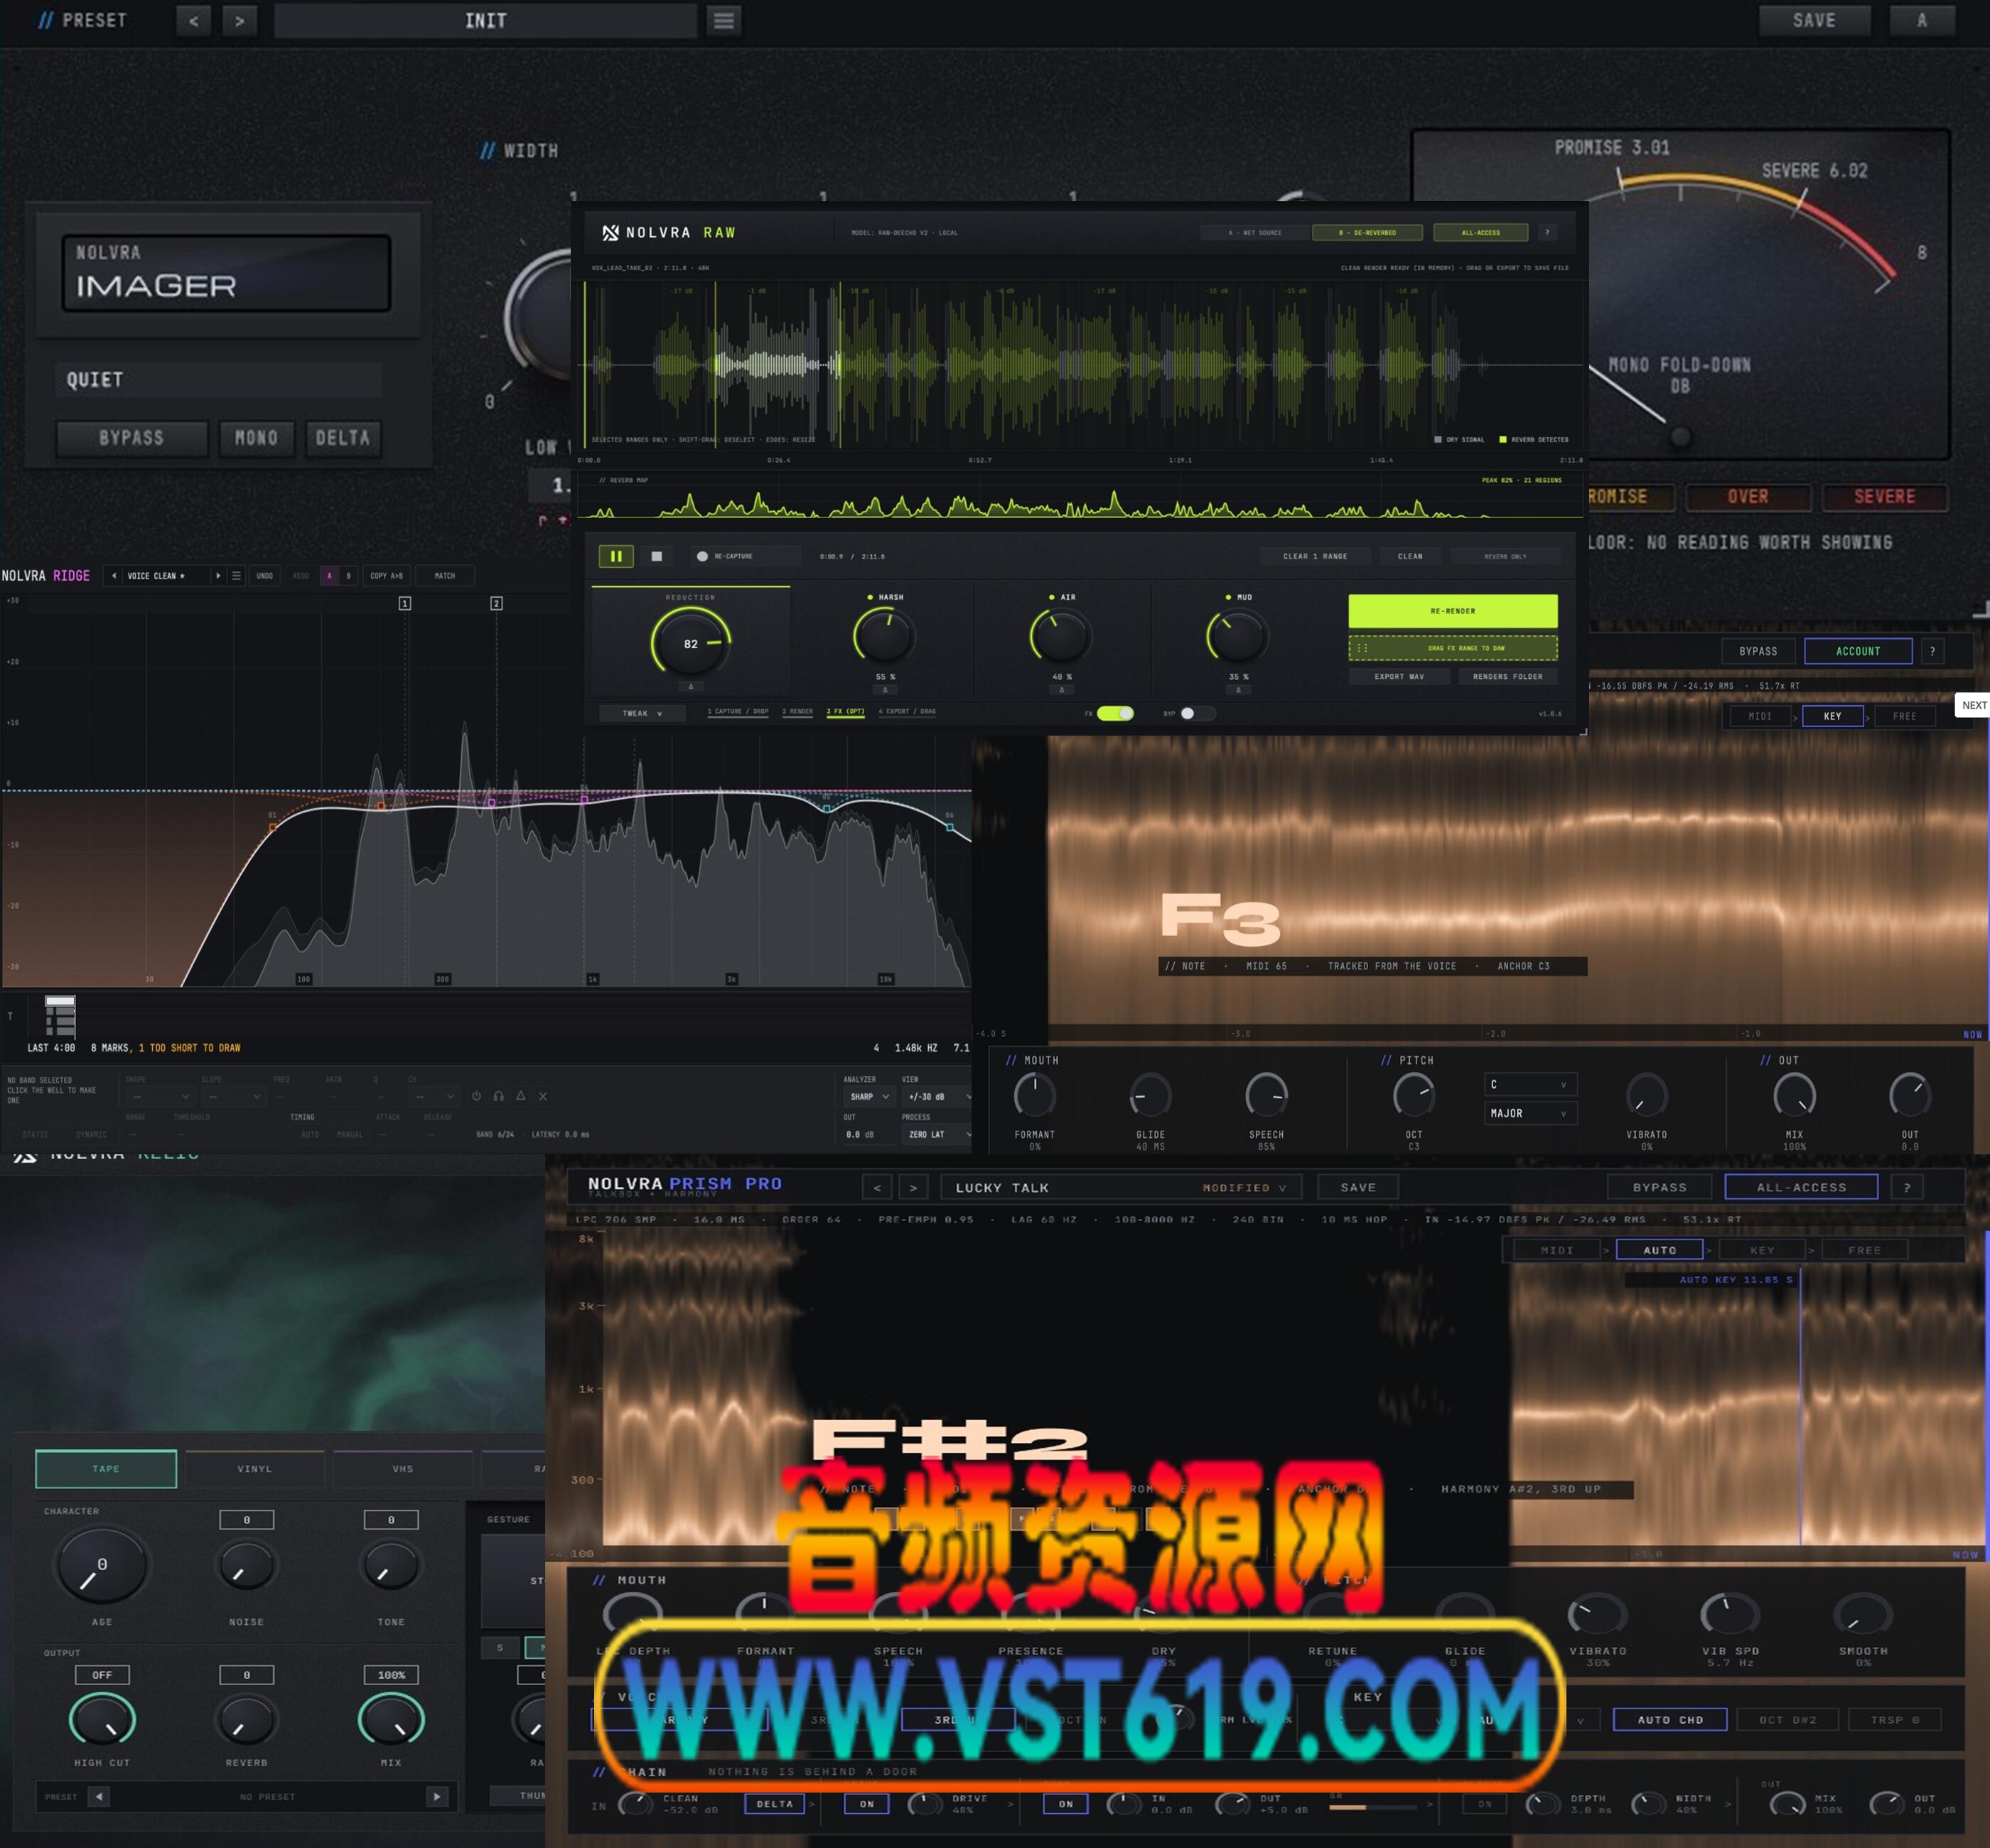
Nolvra Effects All Plugins Bundle v2026包含6款音频插件:立体声像器 IMAGER、Talkbox 工具 PRISM MINI/PRO、去混响 RAW、复古染色 RELIC、共振探测 EQ RIDGE。覆盖立体声处理、人声效果、空间消除、复古质感与智能均衡,一站式混音制作工具包。
翻译:
助您创意不断推进的工具
专精的音频工具,助力制作人从最初构思到最终成品的创作全流程。
6款产品,一个方案
IMAGER、RAW、PRISM MINI、PRISM PRO、RIDGE 和 RELIC。
包含:
1. IMAGER – 立体成像插件
2. PRISM MINI – 人声效果器插件
3. PRISM PRO – 人声效果器插件
4. RAW – AI人声去混响插件
5. RELIC – 复古LoFi效果器/
6. RIDGE – 动态均衡器插件
1. IMAGER
通常,立体声声像插件(Imager)只是向你展示立体声声场的视觉图像,而这款插件则会直接给出具体的数值。
如何判断我的混音在单声道(mono)播放时效果如何?
你的音乐播放的大多数环境都会将其信号合并为单声道,而合并后保留下来的主要是“中置(Mid)”信号。通常的检查方法是切换监听控制器至单声道模式进行聆听,然后再切回立体声,完全依赖听觉判断;这不仅耗时,而且只能给你一个模糊的印象,无法提供精确数据。IMAGER 则不同,它能直接进行测量。它持续监测自身输出端的宽频信号合并(fold-down)损耗,并以分贝(dB)为单位显示数值,同时在数值发生关键变化的两个点标出参考线:3.01 dB(此时相关性降为零,功率损失一半)和 6.02 dB(此时功率损失四分之三)。读数会随混音的变化实时变动,因为这是基于实际输出信号的实时测量,而非预测值;此外,测量点位于插件处理之后,因此显示的数值准确反映了你实际输出的信号状态。如果你想直接聆听测量结果而非仅仅查看数值,只需拨动一个开关,即可将输出信号合并为单声道(合并方式与测量逻辑一致)。
该插件其余部分是一个三频段立体声声像处理器。它提供针对低、中、高频段的宽度控制,以及两个触手可及的分频点调节;低频段的宽度无法超过“单位增益(unity)”状态(即不进行立体声扩展),这一限制直接作用于参数本身,确保宿主软件、预设文件及自动化控制轨道都能识别该限制。Delta(差值)功能仅播放插件处理所产生的差异信号,不包含其他内容。Solo(独奏)功能允许单独监听某个频段的 Mid(中置)或 Side(侧向)信号,共有六种监听模式可选。这三个监听开关的操作不会影响测量读数,因为监听电路位于测量取样点之后。该插件不含人工智能(AI)、学习功能或预分析过程:它的所有处理逻辑都是可以通过数学计算推导出来的。此外,它不会自动修正信号合并后的电平变化。早期版本曾包含自动修正功能,但最终移除了这一机制,因为该功能在那些最不需要修正的音频素材上反而导致了最大的电平波动。相比于静默的自动修正,直接发出警示被认为更合理。这一设计选择带来的直接后果是:在处理实际音频素材时,该插件的指标可能会突破其设定的 3 dB 警戒线——而且它会实时显示这一状态。
工作原理
三个频段,一个指针,一切操作透明可见
每个频段均设有声像宽度(Width)控制,低频段设有硬性上限(hard ceiling),并能实时显示混音在转换为单声道(sum to mono)时损失的量。
指针
它测量插件输出端的全频带单声道合并(fold-down)损耗,并以 dB 为单位显示数值,同时标出两条参考线:3.01 dB(对应功率损失一半)和 6.02 dB(对应功率损失四分之三)。
三个频段
分别针对低、中、高频段的宽度控制,并提供可手动调节的分频点。低频段的宽度控制上限设为“单位增益”(unity,即 100% 宽度),且该限制直接作用于参数本身,因此宿主软件、预设文件及自动化控制轨道均能识别这一设置。
Delta(差值)、Mono(单声道)与 Solo(独奏)
你可以聆听插件处理带来的差异、指针所测量的单声道合并效果,或是单独监听某个频段的 Mid(中置/和差信号中的和信号)或 Side(侧置/差信号)分量。这三种监听模式均不会改变测量读数。
单声道合并(Mono fold-down)
它既不自动修复合并问题,也绝不掩盖问题
无论是夜店音响系统、手机扬声器,还是你的音乐播放时所在的许多房间环境,都会将混音合并为单声道;而在合并过程中保留下来的部分即为 Mid 信号。该插件会在输出端持续测量损失量,并在你调节宽度参数的同时显示 dB 数值。它不会擅自降低宽度设置。
1
3.01 dB
第一条标示线。达到此数值时,全频带相关性(correlation)降为零,且一半的功率在单声道合并过程中损失。
2
6.02 dB
第二条标示线。此时四分之三的功率已损失。
3
读数
读数会随混音的变化而实时变动,因为它是基于实际测量而非预测得出的。此外,测量是在插件处理之后进行的,因此显示的数值始终反映了你实际输出的信号状态。
4
无自动保护(No guard)
早期版本曾具备自动降低宽度的功能,但这会反过来影响测量结果。最终决定认为“发出警告”优于“静默修正”,这一设计决策已定。
Width(宽度)
低频段的宽度上限设为 1(即原始宽度),且该上限位置清晰可见。
包含三个频段(每个频段均配有独立的宽度控制)以及两个触手可及的分频点。低频段的宽度无法超过 1,这一上限直接作用于参数本身(在音频信号输入前即已设定),而非隐藏在内部引擎中的某种“钳制”机制(这种机制往往会导致宽幅度的自动化曲线在触顶时产生静默截断)。这是该插件唯一的实质性保护措施,也是宿主软件能够识别的参数设置。
1
Width(宽度)
0 代表单声道(Mono),1 代表保持原样,2 代表侧向(Side)电平加倍。该参数呈线性比例变化,因此控制旋钮的中心定位点(detent)正好位于行程的中间位置。
2
Low width(低频宽度)
与上述宽度控制相同,但其上限被锁定在 1。根据设计,该频段无法进行加宽处理。
3
Crossovers(分频点)
低频分频点范围为 40 Hz 至 400 Hz,默认设在 120 Hz;高频分频点范围为 800 Hz 至 8 kHz,默认设在 2500 Hz。两者之间始终保持至少 100 Hz 的间隔。
4
Resolution(分辨率)
低频分频点采用了非线性分布设计,使其在低频段(即决定单声道处理的关键区域)能够实现 1 Hz 级别的精细调节。
2. PRISM MINI
将其加载到人声轨道上即可演唱。它内置了载波信号(carrier),只需拥有 Nolvra 账户即可免费获取。
有没有那种不需要额外载波轨道的免费 Talkbox 插件?
PRISM MINI 正是一款内置载波信号的免费 Talkbox 插件。其他免费方案通常都需要先设置载波:你需要在第二条轨道上放置合成器,将合成器声像完全向左、人声完全向右,并汇入同一个立体声总线,然后才能试听乐句的效果。PRISM MINI 则直接从输入的人声中提取音高,因此只需在人声轨道上插入该插件即可使用。它属于 Talkbox 而非声码器(Vocoder),两者的区别在于工作原理:声码器将人声分解为频段,并将该频谱特征赋予合成器声音;而 Talkbox 则是让人声信号通过模拟口腔共鸣的机制进行处理。市面上大多数归类为 Talkbox 的免费插件,其实都属于前者(声码器类型)。
插件面板上设有十个控制旋钮,上方则是预设栏,所有功能均完全开放,无任何禁用或锁定项。FORMANT(共振峰)、GLIDE(滑音)、SPEECH(语音)和 DRY(干声)用于塑造“口腔”形态:包括共振峰位置、载波滑向下一个音符的时长、保留多少辅音细节,以及底层保留多少原始人声音量。DRY 旋钮控制着两条信号路径的混合比例,这两条路径负责输出 Talkbox 效果之下的原始人声成分(如辅音和气流声);旋钮处于中间位置时,即为插件的默认输出电平。OCT(八度)设定内置载波的演唱音域,显示为具体音符而非八度数值。KEY(调性)需手动设置(包括根音及大调/小调),引擎生成的每个音符都会落在这个调性范围内。VIBRATO(颤音)决定长音的音高波动幅度。MIX(混合)调节 Talkbox 效果与原始干声的比例,OUT(输出)则设定插件的总输出电平。Bypass(旁通)是第十一个控制项,位于插件顶部标题栏。插件附带四个出厂预设:CHEST(胸声)、CRY(哭腔)、TEETH(齿音)和 TUBE(管声);这些预设不会覆盖你的调性、音阶、混合比例或输出设置,而 SAVE(保存)功能则允许你将自定义设置与这些预设并列保存。只要拥有 Nolvra 账户即可免费使用,无需试用期:不限时长,功能全开,无需绑定银行卡。
工作原理
包含三个动作,其中之一是“演唱”
这是一个内置载波信号(carrier)的 Talkbox(说话盒)效果器,因此只需将其作为插入式效果器(insert)加载到人声轨道上即可。
加载到人声轨道
它是一种音频效果器,而非乐器。无需加载合成器,也无需预先演奏任何声部。
演唱
引擎会捕捉并提取人声的音高。
手动设置调性
选择根音及大调或小调,所有音符都会被限定在该调性范围内。
载波(CARRIER)
无需预先加载任何内容
无需第二条轨道、总线(bus)或额外的载波源。载波信号内置于插件内部,并根据捕捉到的人声确定音高,因此只需将其作为插入效果器加载到已有的人声轨道上即可。
1
共振峰(FORMANT)
调整引擎塑造声音时所模拟的口腔形态
2
滑音(GLIDE)
载波从当前音符滑向下一个音符所需的时间(而非直接跳变)。旋钮的默认值为 28 毫秒(这是一个经过测定的数值,而非沿用默认值);而当新建实例时,默认的“Tube”模式则设定为 40 毫秒。
3
语音(SPEECH)
决定保留多少辅音细节
4
干声(DRY)
控制两条信号路径的音量:一条是 Talkbox 之外的原始人声(包含辅音和气声)。旋钮中间位置代表插件的基准电平,因此再次打开时会保持上次设定的位置。
5
音符(NOTE)
显示演唱时载波的实时状态:例如 F3、MIDI 65、由人声追踪、基准音(anchor)为 C3。
音高(PITCH)
包含四个预设,且均不会改变你的调性
音高来源有三个,优先级固定:首先是 MIDI(当键盘按住琴键时),其次是手动设置的调性,最后是人声本身。选择根音以及大调或小调,引擎生成的每一个音符都会落在这个音阶范围内。界面上有四个出厂预设槽位——Chest(胸声)、Cry(哭腔)、Teeth(齿音)和 Tube(管乐音色)——它们都不会预先设定你的调性、音阶、混音或输出方式;你可以通过“Save”(保存)功能将自己的设置保存到这些槽位旁边。
1
OCT(八度)
这是内置载波(carrier)在没有其他指令时的默认演唱音区。它以音符形式呈现(新实例默认为 C3),在音符轨道上被称为“Anchor”(锚点)。
2
KEY(调性)
包含根音和音阶(大调或小调)的设置项,均需手动设定。新实例默认为 C 大调。
3
VIBRATO(颤音)
控制长按音符时的音高波动幅度。默认值为 0%(即无颤音),而在四个出厂预设槽位中,只有“Cry”应用了颤音效果。
3. PRISM PRO
将其加载到人声轨道上即可演唱。它内置了载波信号(carrier),引擎会自动捕捉你的音高,并生成与当前调式匹配的和声。
什么是 Talkbox 插件?PRISM PRO 有何独特之处?
PRISM PRO 是一款内置载波并叠加和声功能的 Talkbox 插件。传统的 Talkbox 总是需要先设置载波:加载合成器、准备 Pad 音色、进行信号路由,最后再对着它演唱。PRISM PRO 则内置了载波,只需将其加载到人声轨道上,开口演唱即可发声。其引擎会追踪捕捉到的人声音高,并确保旋律线保持在你的调式内:它综合考量 MIDI 信息、侧链(sidechain)输入的和弦信息以及设定的调式与音阶。最多三路和声会与主唱声部一同通过相同的门限(gate)控制。PRISM PRO 是 Talkbox 而非声码器(Vocoder),两者听感截然不同。声码器将人声分解为多个频段,并将该频谱形态赋予合成器音色;而 Talkbox 则是利用口腔共鸣来塑造经驱动放大的人声信号——这也是为什么许多被归类为声码器风格的经典唱片,实际上使用的是 Talkbox。
工作原理
无需外部连接的 Talkbox
传统的 Talkbox 总是需要先设置载波:加载合成器、准备 Pad 音色、进行信号路由,最后再对着它演唱。PRISM PRO 内置了载波,只需将其加载到人声轨道上,开口演唱即可发声。这就是全部设置步骤。
加载到人声轨道
PRISM PRO 是一款音频效果器,而非乐器插件。它直接作用于已有的人声轨道,并在播放过程中实时处理音频。
演唱旋律
无需 MIDI 声部、键盘或和弦轨道。引擎会追踪捕捉到的人声音高,并在你演唱时实时显示当前锁定的音符。
选择“口腔”音色
包含 12 个出厂预设,这些预设均通过实际演奏录制而成,而非单纯的参数数值设定。你也可以保存自己的预设。
保持调式
确保音高不偏离歌曲调式
对于 Talkbox 旋律线而言,音高漂移半音所带来的糟糕听感,远比完全不使用 Talkbox 还要糟糕。 PRISM PRO 提供了四种决定演奏音符的方式,且优先级固定:依次为 MIDI、检测到的和弦、设定的调式/音阶,最后是仅依据人声音高。具体数据如下:在锁定和弦模式下,输出音高落在和弦内音(chord tone)的概率为 95.5%,而固定音符模式下仅为 36.3%。设定调式和音阶后,输出音高将完全符合音阶要求,不会出现偏离音阶的情况。音高追踪功能可将输出音高保持在所追踪人声音高 0.3 个半音的范围内。当 AUTO(自动)模式因信息不足无法判定调式时,屏幕会显示相应提示且不进行任何量化处理——因为错误的锁定比不锁定更糟糕。
1
MIDI
发送 MIDI 音符,键盘即演奏相应音高。无需量化,因为音高已由你预先选定。
2
AUTO(自动)
将音轨信号输入侧链(sidechain),PRISM PRO 即可识别和弦,并将输出音高锁定在该和弦的构成音上。芯片会显示识别出的和弦名称。
3
KEY and SCALE(调式与音阶)
没有和弦信号输入?只需设定根音和音阶,引擎的所有输出音高都会落在这些设定范围内。AUTO 模式也能根据你的演唱自动推断出这些参数。
三个和声声部,共用一个门限(gate)
绝不会偏离歌曲调性的和声
产品的另一部分。包含三个和声声部,它们与主唱声部共用同一个门限控制,并串联了后续处理链,确保最终输出的声音即为你所需的声音。实时视图显示的是决策过程而非波形:包括你的原始音高、引擎确定的音高以及和声声部,每次显示六秒钟的动态。当无信号输入时,屏幕显示“LISTENING”(正在监听)而非虚构波形图像。
1
最多三个和声声部
包括低三度、高三度和低八度,每个声部均设有独立开关。所有声部均通过与主唱声部相同的门限控制,因此和声也不会偏离音阶。主唱声部的音量始终比和声声部高出 8 到 17 dB。
2
压缩器与合唱效果器
湿信号通路末端设有 LA-2A 风格的压缩器和立体声合唱效果器,两者均可独立旁通(bypass)。默认预设开启压缩器,关闭合唱效果器。单声道求和(mono sum)会带来 0.67 dB 的电平衰减。 3
保留多少原声成分
MIX(混合)用于调节 Talkbox 效果与干声(原始人声)的比例。DRY(干声)则控制着你原始信号中保留的两部分——辅音与气流声——因此,你可以自行决定语音的清晰度。
4. RAW
从任何录音中去除环境声。捕捉音频、选定范围,然后将“干声”版本拖入您的项目中。
工作原理
环境声并非您原始声音的一部分
在糟糕空间录制的人声,或是被他人混响效果淹没的采样——RAW 能去除环境声,还原纯净的干声。
捕捉 (Capture)
捕捉音频。
选择 (Select)
在波形上选定范围。
拖拽 (Drag)
将处理后的纯净版本拖入您的项目。
塑形 (Shape)
调整还原后的声音
REDUCTION(降噪量)用于设定去除多少环境声。HARSH(刺耳感)、AIR(空气感)和 MUD(浑浊感)用于清理环境声残留的瑕疵。REVERB MAP(混响图谱)显示了音频中的混响分布情况,让您能针对性地处理特定片段——选中所需范围,其余部分保持不变。
1
Reduction(降噪量)
设定去除多少环境声
2
Harsh · Air · Mud(刺耳感 · 空气感 · 浑浊感)
清理环境声残留的瑕疵
3
Reverb map(混响图谱)
仅处理需要调整的片段
本地运行 (Local)
数据完全归您所有
RAW 的模型在您的计算机上运行。无需上传任何数据,您的工程内容也不会离开当前会话。导出或拖出的文件均为 32-bit 浮点 WAV 格式,确保您听到的声音与导入 DAW 的声音完全一致。
1
在您的计算机上
模型在本地运行
2
无需上传
工程内容不离开当前会话
3
32-bit 浮点格式
导出和拖出文件保持无损品质
5. RELIC
瞬间为音频增添磁带、黑胶、VHS 或收音机特有的音色质感。
有没有一款免费插件能同时涵盖磁带、黑胶、VHS 和收音机音色?
RELIC 是一款免费的音色插件,通过一个“AGE”(年代感)宏控制旋钮,即可调用磁带、黑胶、VHS 和收音机四种音色。这四种音色各自采用独立的处理流程,而非仅仅是同一算法在不同强度下的变化:每种音色包含六个动态变化的参数,且各自遵循独立的曲线;因此,将 TAPE(磁带)模式的 AGE 设为 40,与将 RADIO(收音机)模式的 AGE 设为 40,会产生截然不同的音色效果。当 AGE 设为 0 时,插件在设计上表现为“直通”(bypass)状态,这意味着它可以一直挂载在信号链上,在未调节 AGE 之前不会对音频产生任何影响。
除了模拟设备本身的音色,插件还营造了空间氛围。NOISE(噪声)功能为每种音色赋予了独特的质感:磁带的底噪、黑胶唱片的表面摩擦与爆裂声、VHS 的底噪与电源嗡嗡声,以及收音机的静电噪音。该噪声模块特意置于 HIGH CUT(高频切除)电路之后,因此即便调暗音色,也不会损失高频空气感。REVERB(混响)仅由一个旋钮控制,采用我们自主设计的混响空间:一种音色偏暗、带有长衰减且高频阻尼明显的空间效果,它是根据工程采样率实时合成的,而非加载预设文件;当旋钮归零时,混响完全不参与信号处理。RAIN(雨声)功能叠加了真实的雨声录音(无缝循环的环境音),而非合成音效。THUNDER(雷声)功能以随机间隔播放真实的雷声,其音量随 RAIN 设置联动,若 RAIN 关闭则雷声静止。STOP(停带)功能位于湿信号链路上,模拟磁带停止时的变速停顿效果,提供三种时长选项。当 MIX(混合)设为 0 时,输出信号与干信号完全一致(位级相同)。
工作原理
四种音色,一个旋钮
磁带、黑胶、VHS 和收音机音色集于一体,由单个 AGE 宏旋钮控制。
选择音色
磁带、黑胶、VHS 或收音机,各对应一个按钮。
调节 AGE
设为 0 时听起来像直通(bypass)信号。这是刻意的设计,而非偶然。
混合音色
MIX 旋钮用于在纯净信号下混合处理后的音色。
音色特性
一个插件,四种风格
磁带、黑胶、VHS 和收音机是四个独立的处理流程,而非同一算法在不同强度下的变化:每种音色包含六个动态变化的参数,且各自遵循独立的曲线。位于核心处理模块后的环境音效会根据所选设备的音色特性进行响应,并随 AGE 旋钮的调节而变化。 1
磁带 (TAPE)
温暖音色边缘,并引入微妙的不稳定性
2
黑胶 (VINYL)
加入灰尘感、表面起伏及磨损质感
3
VHS录像带 (VHS)
柔化画面,伴随低频的电源嗡嗡声
4
收音机 (RADIO)
将信号收窄,呈现广播质感
手势 (GESTURE)
长按以引入“天气”音效
面板上设有一个独立区域,用于控制即兴演奏而非预设的音效。该功能需长按(而非点击)触发;其中的两层“天气”音效均为实地录音,侧重于听觉体验而非视觉呈现。
1
停止 (STOP)
在湿润音色路径(Wet Path)上触发的磁带停止效果,提供三种时长选择
2
雨声 (RAIN)
真实的雨声录音,采用无缝循环的实地录音(Field Loop)而非合成音效
3
雷声 (THUNDER)
真实的雷声,随机间隔触发,并随雨声强度变化
6. RIDGE
按下 SCAN(扫描)按钮。它会标记出检测到的共振点,并显示它们出现的时间。
有没有哪款均衡器能自动帮你找出录音片段中的共振点?
手动扫频寻找“嗡嗡”作响的共振频率,每条音轨大约需要三分钟,而且每条音轨都要重复这三分钟的工序。RIDGE 能自动完成一次扫频。按下 SCAN 后,它会分析音频片段,标记出最多八个共振点,并将这些标记记录在时间轴上——这意味着共振既是一个频率点,也是一个时间点。它之所以能区分共振与正常音乐,并非依据响度:演唱的音符在频谱上也表现为显著高于周围频率的窄峰,且在 27 个实际混音和录音样本中,音符的测量响度甚至高于人为植入的共振信号。区分两者的关键在于时间。音乐是动态变化的,而共振则不随乐曲内容改变;因此,RIDGE 会监测一个 5 秒的时间窗口,仅报告那些持续存在足够长时间的共振点。按下 APPLY(应用)后,这些标记会转化为均衡频段:它们的静态增益保持平直,而衰减(cut)动作则发生在动态范围内——这意味着当特定频率产生共振时,该频段会动态响应(进行衰减),而在不共振时则保持静止。
除此之外,它还是一款功能完备、足以独立完成唱片制作的均衡器。它拥有 24 个频段,每个频段提供 6 种滤波器形状、10 级斜率设置(从 6dB/倍频程到“砖墙式”陡峭衰减)、5 种立体声定位模式(包括 Mid/Side 模式),以及独立的动态处理部分。其动态阈值基于瞬时电平而非滑动平均值,因此在强音段落持续期间,阈值能保持稳定。此版本支持零延迟处理。PROCESS(处理)选项包含自然相位(Natural Phase)和线性相位(Linear Phase)模式;若无法满足所选模式要求,插件会明确提示而非伪装运行——界面栏会显示“MODE FELL BACK”(模式回退)提示。它还配备了具备三级平滑处理功能的分析仪,这通常是同类插件不提供的控制选项。插件包含 453 个参数,自首版发布起即完全公开且锁定,确保今天编写的自动化控制数据在后续所有版本中均能准确读取。RIDGE 不具备的功能列在本页的对比表中:无频谱动态处理、无环绕声路由、无复古设备模拟、也无饱和度处理级。
工作原理
只需三个步骤,其中第一步仅需按下一个按钮:
扫描以发现共振,时间轴记录共振位置,电平匹配确保对比的公正性。 SCAN(扫描)
它会分析音频片段并标记出最多八个共振点。APPLY(应用)功能会将这些标记转换为频段,且只需一次“撤销”操作即可移除所有频段。
时间轴 (The T axis)
标记是基于时间轴定位的,因此一个“环”(ring,即共振点)既代表频率,也代表发生的时间点。同类分析工具通常只显示当前的瞬时状态。
MATCH(匹配)
它会读取你的操作所增加或减少的电平量并显示数值,从而确保 A 与 B 比较时响度一致,而不是让其中一个听起来更响。
SCAN(扫描)
它能自动找出共振点,无需你手动扫频查找。
音符在频谱上表现为高于周围背景的窄峰,因此仅凭响度无法区分共振与正常音乐信号。区分两者的关键在于时间:音乐是不断变化的,而共振则不随演奏内容改变。SCAN 监测一个 5 秒的时间窗口,仅报告那些在该窗口内持续存在足够时间的频率。
1
Sensitivity(灵敏度)
峰值必须高出周围背景多少才会被识别。默认值为 50%,该值基于实测的转折点(knee)设定,而非简单的整数。
2
Min and max(最小与最大频率)
SCAN 监测的频率范围。默认范围为 60 Hz 至 16 kHz,从而排除了音频中的低频轰鸣(rumble)和超高频空气感(air)的干扰。
3
Max count(最大数量)
希望获取的标记数量(1 到 8 个),默认值为 4 个。
4
Apply(应用)
将现有的标记转换为对应的频段。静态增益保持平直,衰减(cut)作用于动态范围之内;这意味着当该频率发生共振时,频段会产生动作,而在不共振时则保持静止。
5
Delete(删除)
移除由扫描生成的频段(仅移除这些频段)。
Dynamics(动态)
阈值是一个固定的电平值。
全部 24 个频段均配备独立的动态处理部分,其阈值设定为具体的 dBFS 电平值,而非频段近期状态的移动平均值。移动平均值会滞后于事件,且往往在响亮信号持续期间就过早释放;而固定电平阈值则能在响亮片段持续的整个过程中保持作用。
1
Threshold(阈值)
可手动输入数值,或让 AUTO(自动)功能估算该频段的常规电平并在此基础上设置偏移量。无论哪种方式,最终设定的都是一个具体的电平值。 2
Range(范围/幅度)
决定频段变化的幅度,顾名思义:当信号超过“阈值(threshold)+ 跨度(span)”时,实际施加的增益量即为此“范围”值。正值会放大该频段,负值会衰减(压低)该频段,零值则无影响。
3
Attack and release(启动与释放)
决定了变化发生的速度以及恢复原状的速度。
4
Sidechain(侧链)
检测器监测该频段的信号特征,其监测范围特意设定得比该频段本身更宽。对检测器信号应用低切(low cut)或高切(high cut)滤波,可以缩小触发该处理的频率范围。
————————————————————————————————————
原文:
Tools that keep your ideas moving
Focused audio tools that keep producers moving from first idea to finished session.
6 products, one plan
IMAGER,RAW, PRISM MINI, PRISM PRO, RIDGE and RELIC.
Includes:
1.IMAGER
2.PRISM MINI
3.PRISM PRO
4.RAW
5.RELIC
6.RIDGE
1.IMAGER
Every imager draws you a picture of your stereo field. This one prints the number.
How do I know if my mix will survive being played in mono?
Most of the rooms your record gets played in will sum it to mono, and what survives that sum is the mid signal. The usual way to check is to switch a monitor controller to mono, listen, switch back, and decide with your ears, which takes minutes and gives you an impression rather than a figure. IMAGER measures it instead. It watches the broadband fold-down loss at its own output, continuously, and prints it in dB against two lines that are drawn where the arithmetic changes: 3.01 dB, the rung where correlation reaches zero and half the power is gone, and 6.02 dB, where three quarters of it is. The reading moves the moment the mix moves, because it is measured and not predicted, and it is taken after the plug-in, so it is always the figure for what you are actually sending out. If you want to hear what it is measuring rather than read it, one switch folds the output down with the same sum the needle uses.
The rest of it is a three band stereo imager. A width control for the low, mid and high band, two crossovers under your hand, and a low band that cannot be pushed past unity, with that ceiling sitting on the parameter itself so your host, your preset and your automation lane can all see it. Delta plays the difference the plug-in is making and nothing else. Solo puts one band’s mid or side on its own, six taps in all. None of the three listening switches can move the reading, because the monitor section sits after the needle’s tap. There is no AI in it, no learning and no analysis pass: every decision it makes is one you can work out on paper. And it does not correct the fold-down for you. An earlier version did, and that guard was measured back out of the product, because it moved the level most on the material it helped least. Warning was judged better than silent correction. The honest cost of that decision is that this plug-in can break its own 3 dB line on real material, and it says so while doing it.
How it works
Three bands, one needle, and nothing done behind your back
A width control per band, a hard ceiling on the low one, and a live reading of what the mix loses when it is summed to mono.
The needle
It measures the broadband mono fold-down loss at the plug-in’s own output and prints it in dB, against two lines: 3.01 dB, where half the power goes, and 6.02 dB, where three quarters of it does.
Three bands
A width control for the low, mid and high band, with the crossovers under your hand. The low band stops at unity and the stop is on the parameter, so your host, your preset and your automation lane can all see it.
Delta, mono and solo
Hear the difference the plug-in is making, hear the mono fold the needle is measuring, or hear one band’s mid or side on its own. None of the three can move the reading.
Mono fold-down
It does not fix the fold-down for you and it never hides it
A club system, a phone speaker and half the rooms your record will be played in sum your mix to mono, and what survives that sum is the mid signal. This plug-in measures what is lost, continuously, at its own output, and prints the figure in dB while you keep both hands on the width. It does not pull the width down on your behalf.
1
3.01 dB
The first printed line. At that rung broadband correlation reaches zero and half the power is gone to the mono sum.
2
6.02 dB
The second. Three quarters of it is gone.
3
The reading
It moves the moment the mix moves, because it is measured and not predicted. And it is measured after the plug-in, so it is always the figure for what you are actually sending out.
4
No guard
An earlier version pulled the width down by itself and it was measured back out. Warning was judged better than silent correction, and that decision is final.
Width
The low band stops at unity, and the stop is somewhere you can see it
Three bands, each with its own width control, and two crossovers under your hand. The low band cannot be pushed past unity and that ceiling sits on the parameter itself, decided before any audio arrives, rather than as a clamp buried in the engine that a wide automation curve would hit silently. It is the only real protection this plug-in carries, and it is the one your host can read.
1
Width
Zero is mono, one is unchanged, two is twice the side level. Linear in the ratio itself, so the centre detent lands in the middle of the control.
2
Low width
The same control with its top at one. It cannot go wide, by design.
3
Crossovers
The low one runs 40 Hz to 400 Hz and opens at 120. The high one runs 800 Hz to 8 kHz and opens at 2500. They are held at least 100 Hz apart.
4
Resolution
The low crossover is skewed so it resolves single hertz near its bottom, which is where the mono decision is actually made.
2.PRISM MINI
Put it on the vocal and sing. The carrier is already inside, and it is yours with a Nolvra account.
Is there a free talkbox plugin that does not need a carrier track?
PRISM MINI is a free talkbox plugin with the carrier built into it. Every other free option asks for a carrier first: a synth on a second track, panned hard left against your voice panned hard right, onto one stereo bus, before you find out whether the phrase works at all. PRISM MINI takes the pitch from the voice it hears, so the setup is one insert on the vocal track. It is a talkbox and not a vocoder, and the difference is the mechanism: a vocoder splits a voice into frequency bands and stamps that shape onto a synth, while a talkbox drives one voice through the resonances of a mouth. Most of the free plugins filed under talkbox are the first thing.
Ten controls stand on the face and a preset strip runs above them, and nothing on it is dimmed or locked. FORMANT, GLIDE, SPEECH and DRY shape the mouth: where it is placed, how long the carrier takes to slide into the next note, how much consonant detail survives it, and how much of your own voice arrives underneath. DRY is one lever over the two paths that carry your own voice out under the talkbox, the consonants and the air, and the middle of the knob is the level the plugin has always had. OCT sets the register the built-in carrier sings in, and it reads as a note rather than as a number of octaves. KEY is set by hand, a root and major or minor, and every note the engine decides on lands inside it. VIBRATO decides how much a held note moves. MIX sets the talkbox against your dry voice and OUT sets the level that leaves the plugin. Bypass is the eleventh control and it sits in the header. Four factory presets ship with it, CHEST, CRY, TEETH and TUBE, and not one of them writes your key, your scale, your mix or your output, while SAVE puts your own settings beside them. It is free with a Nolvra account rather than free for a trial period: no time limit, no feature locks, and no card.
How it works
Three moves, and one of them is singing
A talkbox with the carrier inside it, so the setup is an insert on the vocal.
Insert it on the vocal
It is an audio effect, not an instrument. No synth to load, no part to play first.
Sing
The engine takes the pitch from the voice it hears.
Set the key by hand
Pick a root and major or minor, and every note lands inside it.
CARRIER
NOTHING TO LOAD FIRST
NO SECOND TRACK, NO BUS, NO CARRIER TO LOAD. THE CARRIER LIVES INSIDE THE PLUGIN AND TAKES ITS PITCH FROM THE VOICE IT HEARS, SO THE SETUP IS ONE INSERT ON THE TRACK THAT ALREADY CARRIES YOUR VOCAL.
1
FORMANT
SHIFT THE MOUTH THE ENGINE IS SHAPING THE SOUND WITH
2
GLIDE
HOW LONG THE CARRIER TAKES TO SLIDE INTO THE NEXT NOTE INSTEAD OF STEPPING TO IT. 28 MS IS THE KNOB’S OWN DEFAULT, A MEASURED NUMBER RATHER THAN AN INHERITED ONE, AND TUBE, THE SLOT A FRESH INSTANCE OPENS ON, ASKS FOR 40.
3
SPEECH
DECIDE HOW MUCH OF THE CONSONANT DETAIL SURVIVES
4
DRY
ONE LEVER OVER THE TWO PATHS THAT CARRY YOUR OWN VOICE OUT UNDER THE TALKBOX, THE CONSONANTS AND THE AIR. THE MIDDLE OF THE KNOB IS THE LEVEL THE PLUGIN HAS ALWAYS HAD, SO IT OPENS WHERE YOU LEFT IT.
5
NOTE
THE READING OVER THE STAGE NAMES WHAT THE CARRIER IS DOING WHILE YOU SING: F3, MIDI 65, TRACKED FROM THE VOICE, ANCHOR C3.
ITCH
FOUR PRESETS, AND NONE OF THEM MOVES YOUR KEY
THE NOTE COMES FROM ONE OF THREE PLACES AND THE ORDER IS FIXED: MIDI WHILE A KEYBOARD IS HOLDING ONE, THEN THE KEY YOU SET BY HAND, THEN THE VOICE ALONE. PICK A ROOT AND MAJOR OR MINOR AND EVERY NOTE THE ENGINE DECIDES ON LANDS INSIDE IT. FOUR FACTORY SLOTS SIT ON THE STRIP, CHEST, CRY, TEETH AND TUBE, AND NOT ONE OF THEM WRITES YOUR KEY, YOUR SCALE, YOUR MIX OR YOUR OUTPUT. SAVE PUTS YOUR OWN SETTINGS BESIDE THEM.
1
OCT
THE REGISTER THE BUILT-IN CARRIER SINGS IN WHEN NOTHING ELSE IS TELLING IT WHAT TO PLAY. IT READS AS A NOTE, C3 ON A FRESH INSTANCE, AND THE NOTE LINE CALLS IT THE ANCHOR.
2
KEY
A ROOT BOX AND A SCALE BOX, MAJOR OR MINOR, BOTH SET BY HAND. A FRESH INSTANCE READS C AND MAJOR.
3
VIBRATO
HOW MUCH THE HELD NOTE MOVES. 0% UNTIL YOU ASK FOR IT, AND CRY IS THE ONE FACTORY SLOT THAT DOES.
3.PRISM PRO
Put it on the vocal and sing. The carrier is already inside, the engine finds your pitch, and the harmony lands in your key with it.
What is a talkbox plugin, and what does PRISM PRO do differently?
PRISM PRO is a talkbox plugin with the carrier built in and harmony on top. Every talkbox asks you for a carrier first: load a synth, print a pad, route it in, then sing over it. PRISM PRO ships with the carrier inside, so you drop it on the vocal track, sing, and it plays. The engine follows the pitch of the voice it hears and keeps the line in your key: MIDI first, then the chord it hears on the sidechain, then your key and scale. Up to three harmony voices pass the same gate as the lead. PRISM PRO is a talkbox, not a vocoder, and the difference is audible. A vocoder splits a voice into bands and stamps that shape onto a synth. A talkbox shapes a single driven voice with the resonances of a mouth, which is why the classic records people file under vocoder are mostly talkbox records.
How it works
A talkbox with nothing to plug into it
Every talkbox asks you for a carrier first: load a synth, print a pad, route it in, then sing over it. PRISM PRO ships with the carrier inside. Drop it on the vocal track, sing, and it plays. That is the whole setup.
Drop it on the vocal
PRISM PRO is an audio effect, not an instrument. It goes on the track that already carries your voice, and it plays live while the transport runs.
Sing the melody
No MIDI part, no keyboard, no chord track. The engine follows the pitch of the voice it hears and shows you the note it settled on while you sing.
Pick a mouth
Twelve factory presets, all of them saved by playing the product rather than typed into a table. Save your own beside them.
In key
It does not fall out of the song
A talkbox line that drifts a semitone is worse than no talkbox line. PRISM PRO has four ways to decide which note to play, and the order between them is fixed: MIDI first, then the chord it hears, then your key, then the voice alone. The numbers behind that: with a chord locked, the line lands on a chord tone 95.5% of the time, against 36.3% for a fixed note. With key and scale set, out-of-scale decisions go to zero. The pitch follower sits within 0.3 of a semitone of the voice it is following. And when AUTO has not gathered enough evidence to name a key, it says so on screen and quantises nothing: a wrong lock is worse than no lock.
1
MIDI
Send notes and the keyboard plays the pitch. Nothing is quantised, because you already chose it.
2
AUTO
Feed the track to the sidechain and PRISM PRO hears the chord, then snaps the line to the notes in it. The chip names the chord it heard.
3
KEY and SCALE
No chords to give it? Set the root and the scale and every decision the engine makes lands inside them. AUTO works this out from what you sing.
Three voices, one gate
Harmony that cannot fall out of the song
The other half of the product. Three voices, the same gate as the lead, and a chain behind them, so the sound that leaves PRISM PRO is the sound you keep. The live scene draws the decision, not a waveform: your raw pitch, the note the engine committed to, and the harmony voices, six seconds at a time. When there is no signal it says LISTENING rather than inventing a picture.
1
Up to three harmony voices
A third below, a third above, an octave below, each on its own switch. Every voice passes the same gate as the lead, so harmony cannot fall out of the scale either. The lead stays 8 to 17 dB in front of them.
2
Compressor and chorus
An LA-2A style compressor and a stereo chorus sit at the end of the wet path, each a single bypass. The opening preset has the compressor on and the chorus off. The mono sum costs 0.67 dB.
3
How much of you is left
MIX sets the talkbox against your dry voice. DRY sets the two paths your own signal still travels, the consonants and the air, so intelligibility is your call.
4.RAW
Pull the room out of any recording. Capture, select the range, and drag the dry version into your project.
How it works
The room is not part of your sound
A vocal cut in a bad space. A sample drowned in someone else’s reverb. RAW strips the room and hands the sound back dry.
Capture
Capture the audio.
Select
Select the range on the waveform.
Drag
Drag the clean version into your project.
Shape
Shape what comes back
REDUCTION sets how much of the space goes. HARSH, AIR, and MUD clean up what the room left behind. The REVERB MAP shows the measured reverb across your audio, so you treat only the parts that need it. Select a range, leave the rest untouched.
1
Reduction
How much of the space goes
2
Harsh · Air · Mud
Clean up what the room left behind
3
Reverb map
Treat only the parts that need it
Local
Yours stays yours
RAW’s model runs on your machine. Nothing is uploaded, nothing leaves your session. Exports and drag-outs are 32-bit float WAV, so what you hear is what lands in your DAW.
1
On your machine
The model runs locally
2
Nothing uploaded
Nothing leaves your session
3
32-bit float
Exports and drag-outs stay lossless
5.RELIC
Add tape, vinyl, VHS, or radio character in seconds.
Is there a free plugin with tape, vinyl, VHS and radio in one?
RELIC is a free character plugin that puts tape, vinyl, VHS and radio behind a single AGE macro. The four characters are separate processes rather than one algorithm at four depths: six parameters move per character, each on its own curve, so AGE 40 on TAPE and AGE 40 on RADIO are genuinely different treatments. At AGE 0 the plugin sounds like bypass by design, so it can sit on a chain and cost nothing until you turn it up.
Around the machines sits the room. NOISE gives each character its own surface: tape hiss, vinyl surface and crackle, VHS hiss over the mains hum, radio static. It sits outside HIGH CUT on purpose, so darkening the tone never kills the air. REVERB is one knob and one chamber of our own: a dark space with a long, heavily damped tail, synthesised at your session’s sample rate rather than loaded from a file; at zero it is exactly out of the path. RAIN layers a real rain recording, a seamless field loop, not synthesis. THUNDER rolls real thunder at random intervals, follows the RAIN level, and stays silent when RAIN is down. STOP is a tape-stop pad on the wet path, with three lengths. MIX at zero is bit-identical to your dry signal.
How it works
Four characters, one knob
Tape, vinyl, VHS and radio in one box, driven by a single AGE macro.
Pick a character
Tape, vinyl, VHS or radio, one button each.
Turn AGE up
At 0 it sounds like bypass. That is a design rule, not an accident.
Blend it back
MIX rides the character under a clean signal.
CHARACTER
ONE BOX, FOUR TEMPERAMENTS
TAPE, VINYL, VHS AND RADIO ARE FOUR SEPARATE PROCESSES, NOT ONE ALGORITHM AT FOUR DEPTHS: SIX PARAMETERS MOVE PER CHARACTER, EACH ON ITS OWN CURVE. THE FIELD BEHIND THE PLATE TAKES THE CHOSEN MACHINE’S OWN TONE AND GOES ON ANSWERING AS AGE MOVES.
1
TAPE
WARM THE EDGES AND INTRODUCE SUBTLE INSTABILITY
2
VINYL
ADD DUST, SURFACE MOVEMENT, AND WORN DETAIL
3
VHS
SOFTEN THE IMAGE OVER A LOW MAINS HUM
4
RADIO
NARROW THE SIGNAL INTO A BROADCAST
GESTURE
HOLD IT, THEN LET THE WEATHER IN
THE PLATE KEEPS ONE POCKET FOR THE THINGS YOU PLAY RATHER THAN SET. STOP IS HELD, NOT CLICKED, AND THE TWO WEATHER LAYERS ARE RECORDINGS: THEY ARE HEARD RATHER THAN SEEN.
1
STOP
A HELD TAPE STOP ON THE WET PATH, IN THREE LENGTHS
2
RAIN
A REAL RAIN RECORDING, A SEAMLESS FIELD LOOP RATHER THAN SYNTHESIS
3
THUNDER
REAL THUNDER AT RANDOM INTERVALS, FOLLOWING THE RAIN LEVEL
6.RIDGE
Press SCAN. It marks the resonances it finds and shows you when each one was there.
Is there an EQ that finds the resonances in a take for you?
Sweeping a bell around to find the frequency that rings takes about three minutes a track, and it is the same three minutes every track. RIDGE does the sweep once, by itself. Press SCAN and it listens to the take, marks up to eight resonances, and leaves those marks on a time axis, so a ring is a moment as well as a frequency. The reason it can tell a resonance from the music is not loudness: a sung note is also a narrow peak standing well above its own neighbourhood, and in twenty seven real mixes and takes the notes measured louder than a planted ring did. What separates them is time. Music moves and a resonance does not care what is being played, so RIDGE watches a five second window and reports only what stayed through enough of it. APPLY turns the marks into bands whose static gain is flat and whose cut lives in the dynamic range, which means each one moves when its frequency rings and sits still when it does not.
The rest of it is an equalizer you can finish a record in. Twenty four bands, each with six shapes, ten slope rungs from six decibels per octave up to a brickwall, five stereo placements including mid and side, and its own dynamics section whose threshold is a level rather than a running average, so it stays put under a loud passage for as long as the passage lasts. Zero latency processing in this release. PROCESS lists natural phase and linear phase, and the plugin declares the fallback on screen rather than pretending: the bar prints MODE FELL BACK. An analyzer with three smoothing steps, which is a control the class does not usually give you. 453 parameters, published in full from the first release and locked, so automation written today reads the same in every version that follows. What RIDGE does not have is in the comparison table on this page: no spectral dynamics, no surround routing, no vintage models and no saturation stage.
How it works
Three moves, and the first one is a button
A scan that finds the ringing, a time axis that keeps it, and a level match that keeps the comparison honest.
SCAN
It listens to the take and marks up to eight resonances. APPLY turns the marks it found into bands, and one undo takes all of them back.
The T axis
The marks stay on a time axis, so a ring is a moment as well as a frequency. Every other analyzer in this class shows you only now.
MATCH
It reads how much level your moves added or took away and prints the figure, so A against B is the same loudness rather than a louder one.
SCAN
It finds the ringing so you do not have to sweep for it
A note is also a narrow peak above its own neighbourhood, so loudness alone cannot tell a resonance from the music. What separates them is time: the music moves and a resonance does not care what is being played. SCAN watches a five second window and only reports a frequency that stayed through enough of it.
1
Sensitivity
How far above its own neighbourhood a peak has to stand. It opens at 50%, and that default sits on a measured knee rather than on a round number.
2
Min and max
The window SCAN looks in. It opens at 60 Hz and 16 kHz, so the rumble under the take and the air above it are out of the argument.
3
Max count
How many marks you want back, one to eight, and it opens at four.
4
Apply
Takes the marks that are standing and writes a band for each one. The static gain stays flat and the cut lives in the dynamic range, so the band moves when that frequency rings and sits still when it does not.
5
Delete
Removes the bands the scan made and only those.
Dynamics
The threshold is a level, and it stays put
Every one of the 24 bands carries its own dynamics section, and the threshold is a level in dBFS rather than a running average of what the band was just doing. A running average chases the event and lets go while the loud thing is still loud. A level stays under a loud passage for as long as the passage lasts.
1
Threshold
Type one, or let AUTO estimate what this band’s level ordinarily is and offset it from there. Either way it is a level.
2
Range
How far the band moves, and it means what it says: at threshold plus span the applied gain is the range, exactly. Positive opens the band, negative ducks it, zero costs nothing.
3
Attack and release
How fast it gets there and how fast it comes back.
4
Sidechain
The detector listens to the band’s own shape, deliberately wider than the band. A low cut or a high cut on that detector narrows what sets it off.
VST619音频资源网收集整理!
请登录后查看评论内容